
PhoneBox is an open-source project that turns an old Android 5+ phone into a customizable desk panel and touch control deck for Windows, Linux and macOS, pairing an Android app with a desktop agent built on .NET. It offers 126 widgets and 30 templates in 13 languages covering PC stats, AI coding sessions (Claude Code and Codex, including quota tracking and remote permission prompts), media, and Home Assistant automation, connecting over USB or Wi-Fi without any cloud service. The repo was created 13 days ago and has drawn 4130 stars, averaging 318 stars per day.
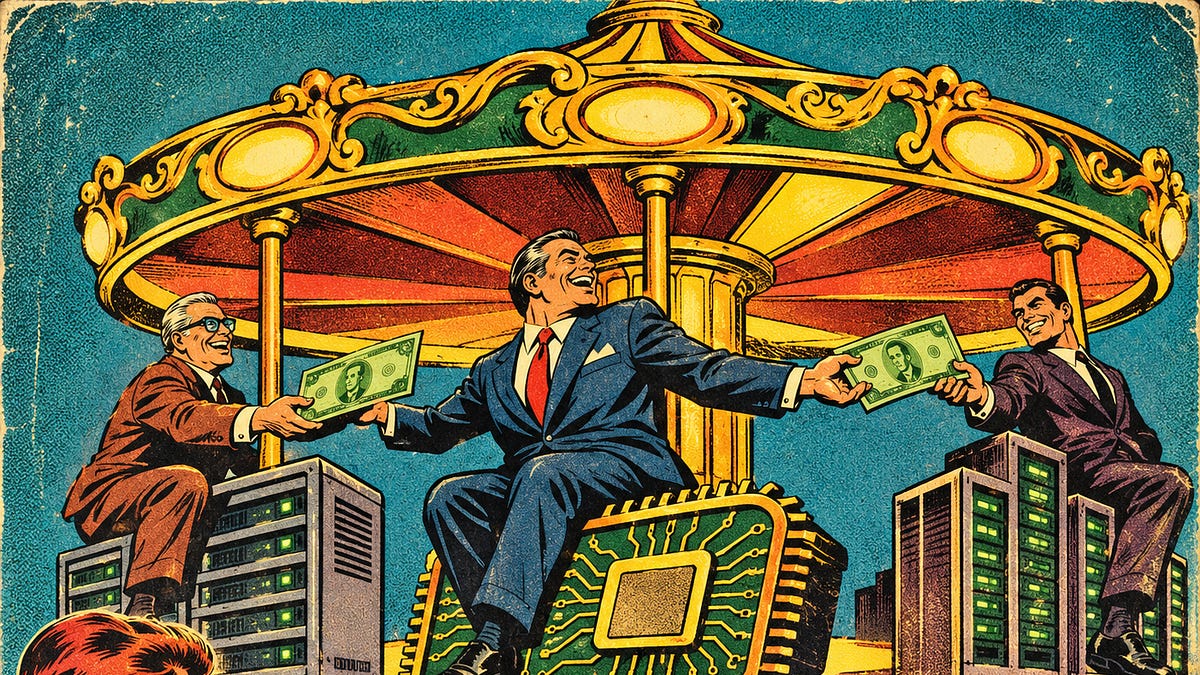
Anthropic went public with a record $81.3 billion IPO, closing at $97.17 for a roughly $1.27 trillion valuation, while Google, Nvidia, AMD, Broadcom, Micron, Microsoft and TSMC bought another $26 billion in stock. The author argues AI demand is partly circular: Anthropic has committed about $900 billion in compute spending through 2045, about 44% of its revenue flows through cloud marketplaces, BIS found 55.2% of AI investment from 2021 to 2025 came from other AI firms, and the IMF counts about $300 billion in equity and $650 billion in debt tied to $1.4 trillion in promised purchases.
After 12 days and 226 sessions, the author's flat MEMORY.md had bloated to 30.9 KB (about 7,700 tokens) per chat, and a naive 8-fact injection cap evicted all 8 architecture and 4 UX invariants. Rebuilding a zero-database Markdown + JSONL memory in the open-source agy-hq setup, the author shares five key mechanisms, including role-aware startup budgets, deterministic guardrail retention instead of usage-based decay, nightly cross-checked writes, a curated Wiki with pure-Go BM25 search, and taint quarantine against indirect prompt injection, plus how five major labs' cross-session memory approaches converge and differ.
Patronus AI measured prompt injection through natural claims in emails/tickets against 9 decision models: one fixed sentence flipped 9-27% of correct decisions, and 12 adaptive attempts reached 48-80%, with no model resisting; model accuracy didn't predict robustness (the most accurate ranked 5th of 9), and redefining policy labels worked better than fake authority or fake system messages. A separate checker on untrusted text that routes suspicious cases to humans raised scores to 94.7-98.6 out of 100, at the cost of about 14% of harmless cases going to review.
The author measured VRAM usage of Gemma 4 E4B, Qwen3.5 9B, and Qwen3.8 27B on an RTX 3060 12 GB using LM Studio (llama.cpp CUDA) at Q4_K_M with full GPU offload. Gemma 4 E4B used 4.51 GB at 4K context and 74 tok/s; Qwen3.5 9B used 6.66 GB at 54 tok/s; Qwen3.8 27B didn't fit. Hybrid models barely grow with context since Qwen3.5 keeps a KV cache on only 8 of 32 layers (~0.034 GB per 1K tokens), and Gemma 4 E4B keeps about 2.8B of its per-layer embeddings in system RAM. The author built a free browser-based calculator covering ~40 models at Q4/Q5/Q8/FP16 across 54 GPU cards, estimating weights plus KV cache plus ~0.6 GB runtime, within 1% of the measurements.

Tencent's Hy team releases Hy4, a new-generation MoE multimodal flagship model on Hugging Face supporting text, image, and video understanding. The language backbone has 770B total parameters with 49B activated per token, a 1M context length, and Gated DeepSeek Sparse Attention with IndexCache; a 3.3B DFly2 drafter supports speculative decoding. Few-shot pretraining evals show Hy4 Base scoring 91.6 on MMLU and 73.9 on MMLU-Pro.

Ajay K Meena released the open-source local clipping engine NeonClipping on GitHub, which turns YouTube/Twitch/Kick videos or local MP4 files into captioned 1080x1920 vertical clips in about two minutes, fully running on the user's machine with no account or upload needed. Fast mode downloads audio only and reads YouTube word-timed captions as transcript (falling back to a local Whisper), scores loudness jumps and 2-4 kHz raised-voice energy, then lets a local LLM via Ollama score moments and write titles and hooks, and downloads only the chosen sections to render clips. Deep mode adds optical-flow motion and cut density. On an RTX 2060, an 85-minute YouTube stream took 97 seconds and a 3-hour Twitch VOD took 136 seconds in Fast mode; ratings from 5-star feedback refit signal weights loca…
Reverb-TTS is an open-source zero-shot voice cloning TTS that runs in the browser on WebGPU, reaching 22x realtime on an M4 Pro via MLX.



