📄 Paper | 📊 Data | 💻 Code
Today we’re releasing Old Ideas, Novel Problems, a new study of how reliably large language models can evaluate the novelty of scientific research ideas. Alongside the paper, we’re publishing a benchmark, data, and code for testing novelty judges, plus an automated pipeline researchers can use to build new evaluation sets.
At Ai2, we’ve been developing AI systems that support different parts of scientific discovery. DataVoyager helps researchers explore and analyze structured data, AutoDiscovery generates and tests hypotheses, and Theorizer synthesizes evidence across large bodies of literature into candidate scientific theories. Together with Asta, these projects point toward systems that can help researchers move from understanding prior work to proposing, testing, and refining new ideas.
But generating research ideas is only part of the challenge of automating scientific discovery. Those ideas also need to contribute something genuinely new, which means these systems need a way to distinguish a novel direction from one that mostly repackages existing work.
That judgment is often handed to another LLM—what we call a novelty judge. Novelty judges assess whether a research idea is new relative to prior work, either on its own or in comparison with another idea. There’s no standard way to build one; research teams choose a model, prompt, evaluation format, reasoning budget, and sometimes a literature-retrieval system. Those choices can materially affect the verdict. Yet these judges are often validated only on human-written papers rather than the AI-generated ideas they are actually meant to evaluate.
Our new benchmark results suggest novelty evaluation itself is far from reliable. Across six LLM judges – GPT-5.1, GPT-5.2, GPT-5.4, Claude Sonnet 4.5, Claude Opus 4.5, and Claude Opus 4.6 – seemingly small changes to the evaluation setup produce dramatically different judgments of the same ideas. In one experiment, changing just a few words in a prompt shifts a model’s accuracy in identifying which of two ideas is more novel by more than 50 percentage points. Retrieval and additional reasoning do not consistently improve judgments, and two purpose-built novelty evaluation systems perform worse than a simple prompted Claude Opus 4.6 baseline.
If AI is going to play a larger role in scientific discovery, we need more dependable ways to tell whether it is actually proposing something new. Our work provides tools for studying that problem, while showing how much remains unresolved.
Building a benchmark for novelty judges
To test how reliably novelty judges can distinguish more novel research ideas from less novel ones, we first needed examples where there was strong evidence about the originality of the underlying scientific contribution.
So we built an automated pipeline around ICLR 2026 peer reviews. Rather than treating paper acceptance as a proxy for novelty, we mined the reviews themselves for passages where reviewers explicitly discussed a contribution’s originality. That distinction is key; a paper can be accepted without being particularly novel as long as it is strong enough in other aspects. Likewise, a rejected paper with an original contribution can have other weaknesses.
We created a high-novelty pool of 154 human-authored research ideas by selecting accepted papers in the top-rated 10% of their ICLR research area whose reviewers positively identified novelty and where no reviewer disputed it. We applied the reverse criteria to build a lower-novelty pool: 145 ideas from rejected papers in the bottom 10% whose reviewers raised originality concerns without any reviewer positively identifying novelty. In a separate check of the review-mining process, an annotator agreed with the extracted novelty-signal polarity in 47 of 50 cases; none of the disagreements would have changed whether a reviewer was counted as praising or disputing the paper’s novelty.
Together, these two pools form our first evaluation setting, Human-Only, which tests whether novelty judges can tell apart human-authored ideas with strong evidence of higher or lower novelty. But in practice, novelty judges are increasingly being used to evaluate AI-generated ideas. So we created a second setting, Human+Generated.
For this pool, we paired the same 154 validated human ideas with 154 ideas produced by a simple LLM generator. We assumed the generated ideas were less novel than their human-authored counterparts; these are weak labels, not verified judgments for every idea. The generator received only a research area and an instruction to propose a novel idea, with no literature search, tools, iteration, or feedback. This gave us a conservative comparison between ideas from a basic generator and contributions from top-10% ICLR papers whose reviewers had explicitly endorsed their originality.
As additional checks, an expert independently reviewed 30 Human+Generated pairs, heavily weighted toward cases our strongest judge got wrong, and we rewrote the human- and AI-generated ideas into a common structure to test whether judges were simply reacting to differences in writing style. The expert preferred the human idea in all 30 pairs and judged none of the generated ideas novel.
Importantly, many of our core findings don’t depend on the labels at all. If two reasonable evaluation setups give opposite answers for the same pair of ideas, that disagreement itself reveals instability.
Small changes can produce very different verdicts
Using our collections of human-authored and AI-generated research ideas, we tested how well six LLM judges – GPT-5.1, GPT-5.2, GPT-5.4, Claude Sonnet 4.5, Claude Opus 4.5, and Claude Opus 4.6 – could evaluate novelty through both pointwise (i.e., absolute novelty ratings) and pairwise (i.e., comparing two ideas to find the most novel) comparisons. We varied one factor at a time: the prompt, reasoning budget, whether the judge could see related papers, how the ideas were formatted, how many judgments were combined into a final verdict, and – for AI-generated ideas – which model generated them.
The largest shifts in performance came from how we prompted the model to judge novelty.
For example, we showed GPT-5.4 the same Human+Generated pairs – each containing one validated human-authored idea and one AI-generated idea – with two prompts. One prompt told the model that reviewers had found exactly one idea in each pair to be novel and asked it to identify which one; the other simply asked which idea was novel. When we switched to the simpler prompt, accuracy dropped from 93.5% to 40.9% – below chance – and the model changed its verdict on more than half of the same pairs.
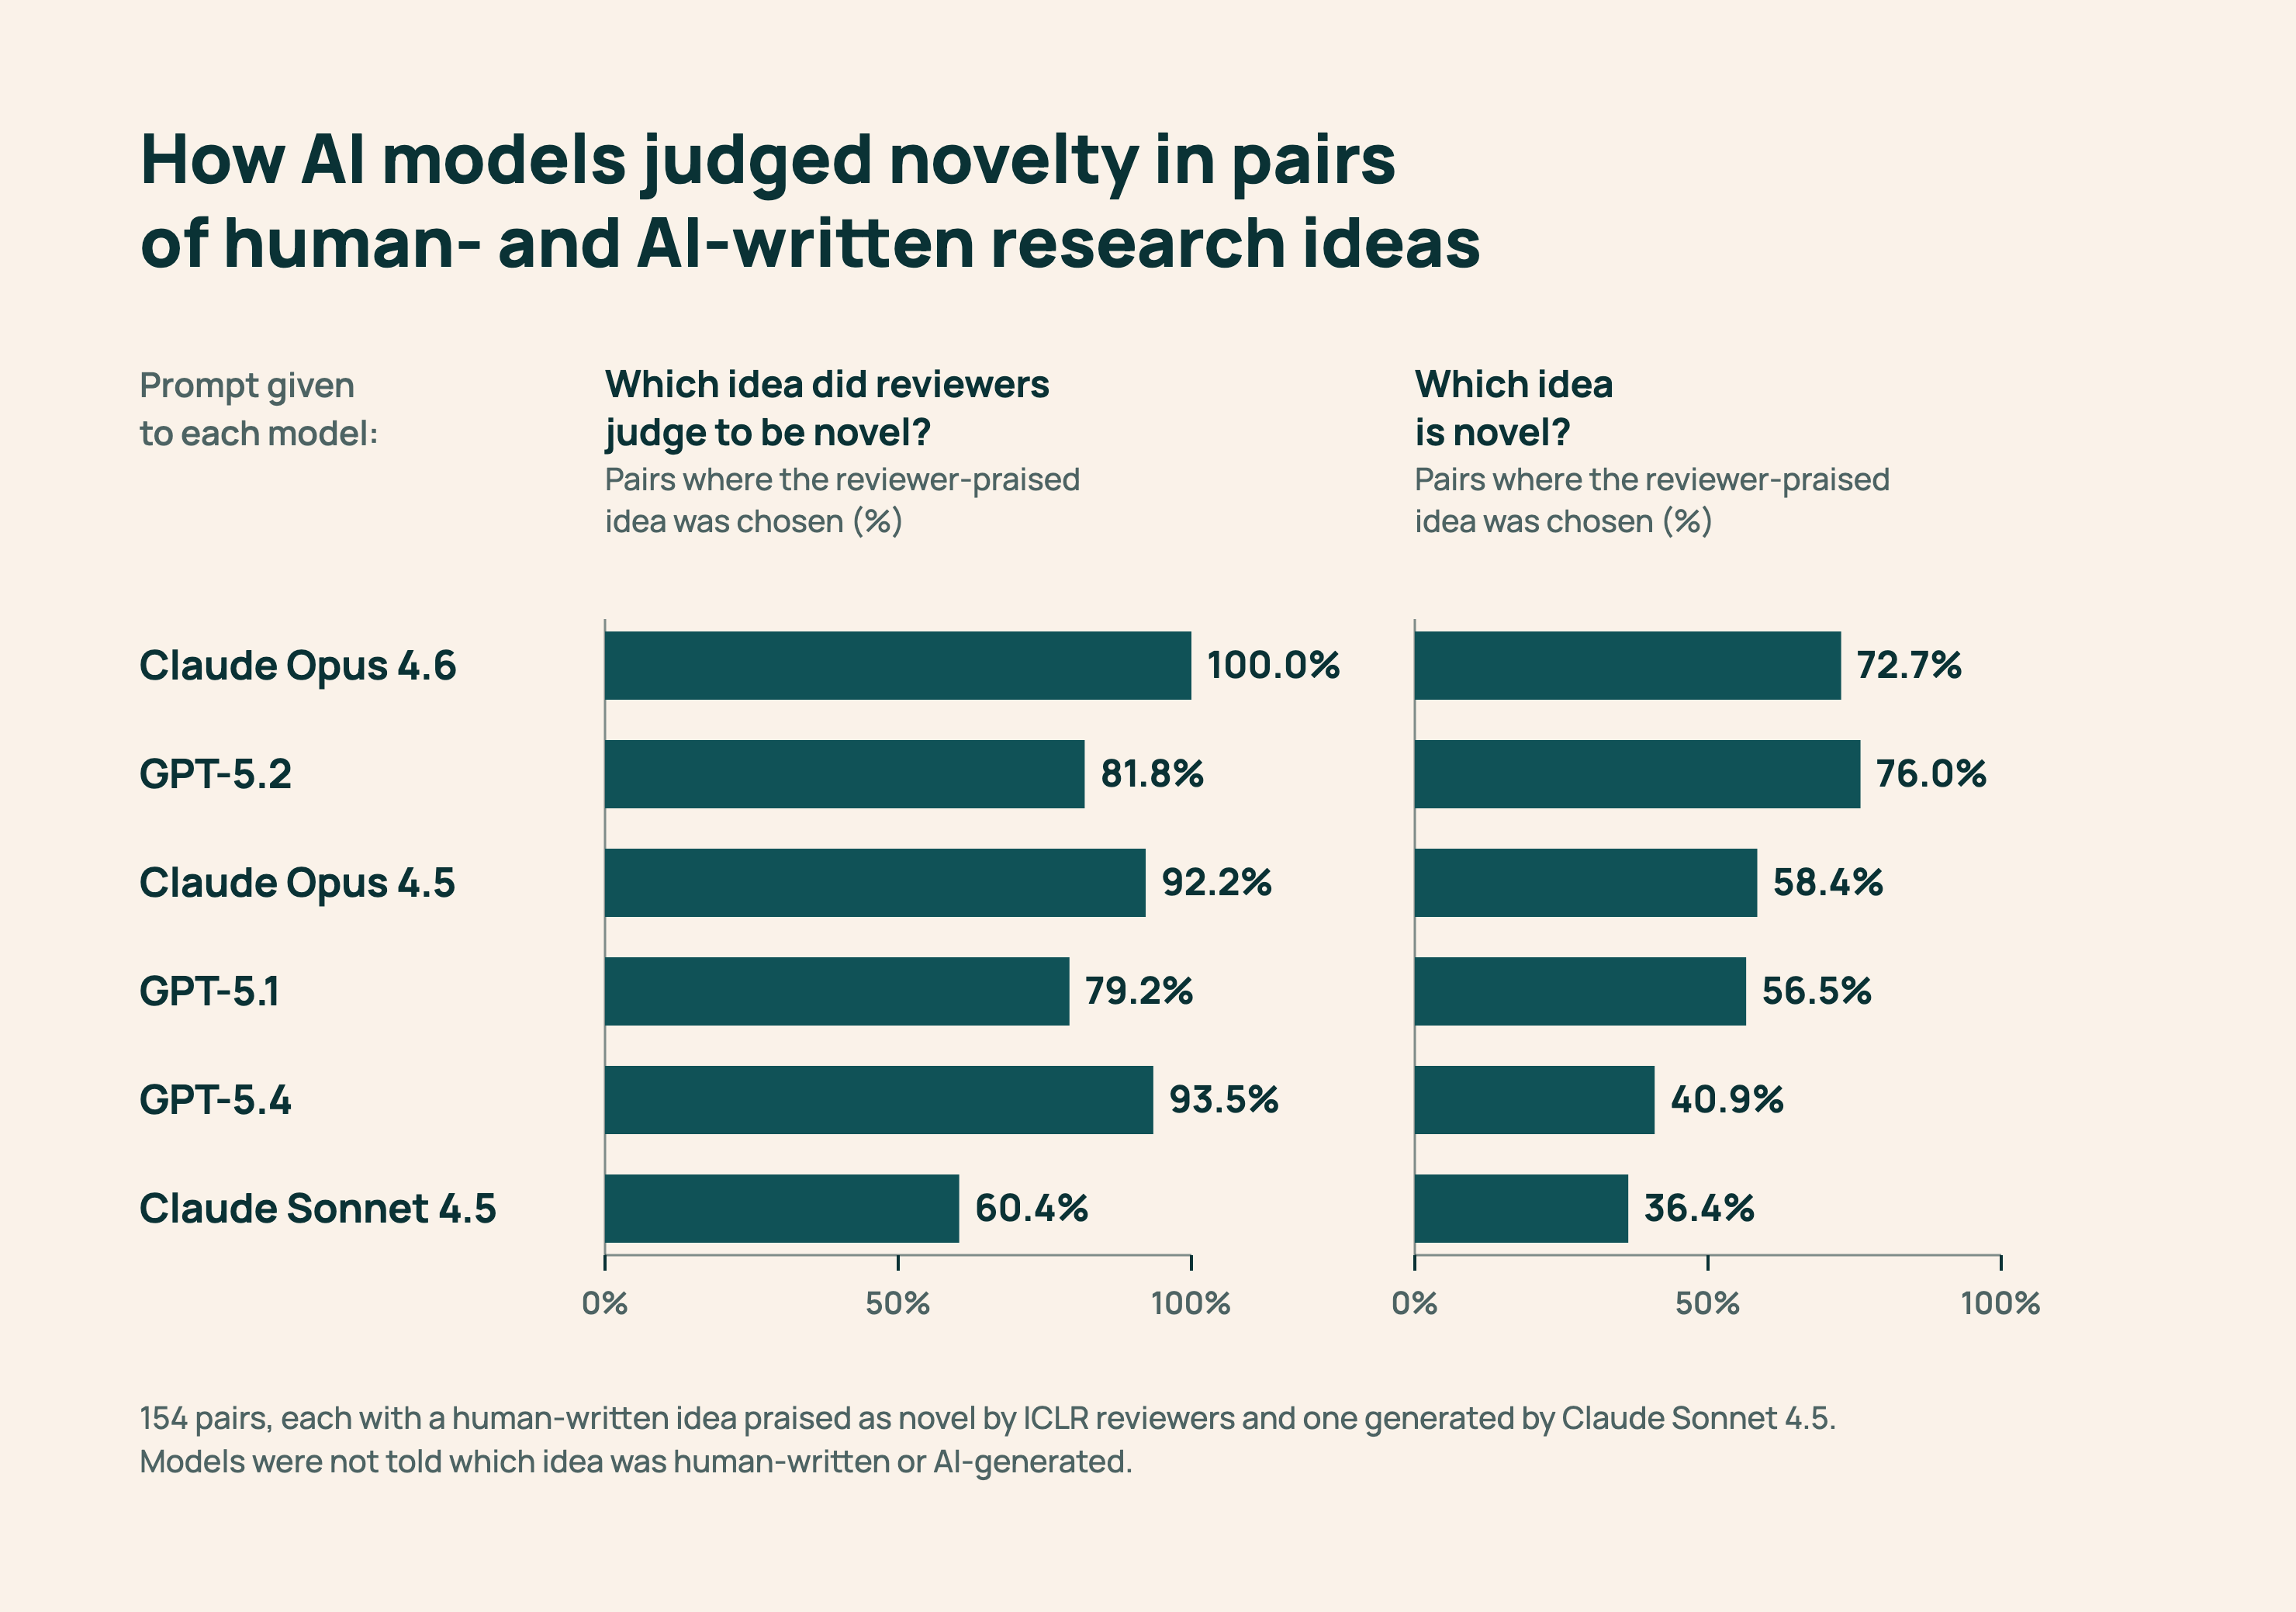
By contrast, the same prompt change shifted accuracy by only about seven percentage points on the Human-Only dataset, which pairs human-authored ideas with stronger and weaker evidence of novelty. That suggests a novelty judge can appear relatively stable on human-authored research but behave very differently on AI-generated ideas.
That said, human-authored ideas weren’t immune. We saw substantial shifts on the Human-Only dataset as well; the same change moved Claude Opus 4.6 accuracy by 21 points. The shifts were just less severe than on the AI-generated ideas.
There was also no universally better prompt. For example, when judging ideas individually, dropping an instruction that warned judges not to treat trivial or incremental contributions as novel improved accuracy for some judges while reducing it for others. A prompt that works well for one model may not transfer to another, in other words.
We also tested a common use of novelty judges: comparing ideas from two AI generators. We paired ideas from Claude Opus 4.5 with Claude Sonnet 4.5, and GPT-5.4 with GPT-5.1. Across the tested prompt changes, roughly a quarter to a third of verdicts changed on average across six judges. This disagreement can be measured without assuming which generator produces more novel ideas, showing how the choice of judge prompt can affect comparisons between ideation systems.
More search and reasoning didn’t necessarily produce better novelty judgments. We gave GPT-5.6 Sol an extra-high reasoning budget and live, iterative search restricted to arXiv, then compared it with standard-retrieval judges that each saw five pre-retrieved abstracts. (All judges in this comparison ran once per idea on Human+Generated.) The agentic judge scored 0.78 macro-F1 – 11 points behind Claude Opus 4.6 at 0.89, and in roughly the same range as simpler Claude Opus 4.5 and GPT-5.4 setups – while costing roughly 10× more per decision at current API prices. (In this context, macro-F1 measures how well a judge identifies novel and non-novel ideas; higher is better.)
Purpose-built evaluators weren’t more accurate either, despite costing substantially more. On the Human+Generated set, a simple Claude Opus 4.6 prompt using low reasoning and majority voting across three calls achieved 0.854 macro-F1 at a total evaluation cost of $2.59. By comparison, Idea Novelty Checker, a literature-grounded retrieval and reranking pipeline, scored 0.642 at $30.66, while Sakana AI’s AI Scientist, whose novelty evaluator iteratively searches Semantic Scholar, scored 0.772 at $82.05. (Both dedicated evaluators used Claude Opus 4.6, with one call per decision.)
In other words, the simple prompted baseline was both more accurate and considerably cheaper than either purpose-built system.
Taken together, these results suggest that novelty evaluation is particularly brittle on the AI-generated ideas these systems are increasingly being asked to judge.
Toward more reliable evaluation of novel research
Our results suggest that LLM-based novelty evaluation remains a major open problem. Judges that appear reliable on human-authored research may behave differently on AI-generated ideas; prompts that help one model can hurt another; and more search or compute does not necessarily produce more consistent judgments.
Future work should test judges on the kinds of ideas they will actually evaluate, measure sensitivity across prompts and models, improve how prior literature is incorporated, and build benchmarks that can evolve as the scientific literature grows and AI systems improve. Our benchmark and reusable data pipeline are a starting point—researchers can apply them to new peer reviews, other scientific communities, and future generations of novelty judges.
Automated ideation depends on more than generating plausible research directions; we also need ways to tell when those ideas are genuinely new. By making the weaknesses of current novelty judges easier to measure, we hope this release helps researchers build more robust ways to evaluate AI-generated research ideas.
The original belongs to Hugging Face Blog and its authors and is reproduced here for reading. To have it removed, write to support@aisa.one.

 Studio
