在 AWS 上构建 AI 智能体的团队使用多种框架,包括 LangGraph、LangChain、Strands Agents 和 Amazon Bedrock AgentCore。每个框架都以自己的方式记录智能体的执行过程,因此消息、工具调用以及智能体之间的交接结构各不相同。评估工具往往遵循相同的界限:团队针对单一框架的追踪格式构建指标、评分逻辑和结果存储,当切换框架或在多个框架上运行智能体时,他们必须重新构建这些内容。
这种耦合使得回答一个基本的开发问题变得更加困难:对提示词(prompt)、模型或工具的更改是否提升了智能体的性能?回答这个问题需要跨智能体版本的一致指标,以及与过去结果进行比较的共同记录。智能体质量还涵盖多个维度,而单一的准确率分数无法捕捉这些维度:工具调用、响应质量、负责任的人工智能(Responsible AI)、性能、多轮对话、多智能体协调和推理。
在本文中,我们介绍通用智能体评估框架(Universal Agent Evaluation Framework, UAEF)。来自电信、医疗保健和金融服务行业的 12 家组织的客户使用 UAEF 以一套一致的指标评估他们的 AI 智能体,并在发布前比较智能体的不同版本。UAEF 是一个与框架无关的评估系统:它使用适配器将来自各个框架的追踪数据转换为通用格式,然后使用 36 种内置指标对这 7 个维度的追踪数据进行评分。它将结果存储在 Amazon DynamoDB 和 Amazon Simple Storage Service (Amazon S3) 中,并生成报告和见解,以指导智能体的下一次迭代。本文介绍了 UAEF 的工作原理,提供了选择指标和准备数据集的操作指南,并为每个支持的框架提供了可运行的笔记本链接。
UAEF 是一个与框架无关的 AI 智能体评估系统。它对团队已有的智能体进行评分,且在支持的框架和运行时环境中采用相同的方式。UAEF 接受两个输入:待测试的智能体和用于运行该智能体的数据集。数据集为每个测试用例提供输入,并且还可以包含标准答案(ground-truth answers),即每个输入的预期输出。标准答案是可选的,只有那些将智能体响应与参考内容进行对比的指标才会使用它。为了评估工具调用,标准答案还必须包含每个测试用例预期的工具调用:智能体应调用哪些工具、调用的顺序以及使用的参数。此后的一切操作都在 UAEF 内部完成。
图 1 展示了单次评估的路径,从输入到报告和见解。首先,适配器读取智能体的原生执行记录,包括其消息、工具调用和智能体间的交接,并将其规范化为唯一的规范追踪(canonical trace),以便无论智能体由哪个框架生成,后续步骤都保持一致。接下来,在数据存储之前,UAEF 会对追踪数据进行个人身份信息(PII)筛查,例如电子邮件地址、电话号码和信用卡号。随后,评估引擎根据 7 个质量维度中的 36 种内置指标对追踪数据进行评分。当您持久化一次运行(run)时,UAEF 会将其作为实验记录在 Amazon DynamoDB 和 Amazon S3 中:Amazon DynamoDB 保存用于列表显示和比较的每次实验的元数据,而 Amazon S3 保存完整的结果。有了存储的运行记录,团队可以将智能体版本与基线进行比较以检测回归(regressions),并生成解释变化原因的报告和见解。这些报告形成了闭环:团队评估智能体,了解哪些部分出现退化或改进,修改提示词、模型或工具,然后再次进行评估。
追踪数据有两种方式进入 UAEF。如果已经存在(来自过去的运行、日志或可观测性存储),则将其交给 UAEF,匹配的适配器会对其进行规范化。如果不存在,UAEF 会为您调用智能体:给定运行时 Amazon Resource Name (ARN) 或 HTTP 端点,它会针对数据集中的每个输入调用智能体,收集响应,并一步完成适配。无论哪种方式,输出都是相同的 AgentTrace。
评估引擎在 7 个质量维度上对规范追踪进行评分,每个维度捕捉了单一准确率数字所掩盖的智能体行为的独特方面。工具调用衡量智能体是否选择了正确的工具、以合理的顺序调用它们并传递了有效的参数。响应质量衡量最终答案是否相关、完整、准确,并且基于提供的上下文而非幻觉生成。
负责任的人工智能衡量安全性、偏见、毒性和对提示注入的抵抗力。性能衡量运营成本的延迟、令牌使用和吞吐量。多轮对话衡量智能体维持对话的能力,包括跨轮次的上下文保留、连贯性和目标完成情况。多智能体衡量协作系统中智能体之间的协调,例如任务委派和工作分工。推理衡量智能体思维链的内部逻辑,包括一致性和无谬误性。
每个维度由 36 种内置指标中的一种或多种计算得出,每个指标返回 [0, 1] 区间内的标准化分数,其中 1 为最佳,因此维度和整体结果共享同一尺度。指标分为两类。确定性指标直接从追踪数据和标准答案计算分数,并在重复运行时精确复现。大语言模型(LLM)作为裁判的指标通过对 Amazon Bedrock 上的裁判模型进行提示,来评分那些难以用封闭形式定义的质量属性,例如响应相关性或安全性。您还可以添加自定义指标或利用 RAGAS 和 DeepEval 集成。
由于裁判指标将智能体自身的输出反馈回提示词中,该内容被视为不可信输入:能够影响其裁判的智能体也能影响其自身的分数。评分标准与内容分开发送,并对内容进行转义处理,使其无法突破定界符并被解读为指令。每个裁判响应都会经过严格解析,且必须引用其所评分内容的逐字片段。如果找不到证据的分数将被拒绝而不是记录。裁判分数是评估信号,而非安全决策,不应作为安全控制的门槛。对于智能体本身在运行时的强制执行,请在其各自的调用路径中应用 Amazon Bedrock Guardrails。完整模型请参阅 SECURITY.md。
Python 库还建模了更细粒度的结构。一个实验包含多次运行(runs),每次运行记录正在测试的智能体设计:框架、模型、工具、系统提示词和参数。一次运行还可以记录配置快照和 Git 提交。您可以将一次运行标记为该实验的基线。这将每个分数与其产生的更改联系起来,无论是新提示词、不同模型还是新增工具。
比较基于存储的每个指标的平均值进行。对于两次运行共有的每个指标,比较引擎计算绝对变化和百分比变化。然后,它使用可配置的阈值(默认为 5%)将该指标分类为回归、改进或未变化。在一次调用中可以比较多次运行与单个基线。回归检测器还会为每次回归分配严重程度:轻微(5–10%)、中等(10–20%)或严重(超过 20%)。它按维度对回归进行分组,从而显示例如提示词更改是否影响了工具调用但未影响响应质量。
在 Web UI 中,“Compare”(比较)选项卡列出存储的实验,并按框架或数据集进行过滤。您选择两个或多个实验。第一个用作基线,UI 显示每个指标的分数,并高亮显示回归和改进。UI 调用相同的库比较引擎,因此结果与 Python API 返回的结果一致。
查看原文
Teams building AI agents on AWS use a range of frameworks, including LangGraph, LangChain, Strands Agents, and Amazon Bedrock AgentCore. Each framework records agent execution in its own way, so the structure of messages, tool calls, and handoffs between agents differs from one to the next. Evaluation tooling tends to follow the same boundaries: teams build metrics, scoring logic, and result storage against a single framework’s trace format, and they must rebuild them when they switch frameworks or run agents on more than one.
This coupling makes a basic development question harder to answer: did a change to the prompt, model, or tools improve the agent? Answering it requires consistent metrics across versions of an agent and a shared record of past results to compare against. Agent quality also spans several dimensions that a single accuracy score does not capture: tool calling, response quality, responsible AI, performance, multi-turn conversation, multi-agent coordination, and reasoning.
In this post, we introduce the Universal Agent Evaluation Framework (UAEF). Customers across 12 organizations in the telecom, healthcare, and financial services industries used UAEF to evaluate their AI agents with one consistent set of metrics and compare agent versions before release. UAEF is a framework-agnostic evaluation system: it uses adapters to convert traces from each framework into a common format, then scores those traces with 36 built-in metrics across 7 dimensions. It stores the results in Amazon DynamoDB and Amazon Simple Storage Service (Amazon S3) and generates reports and insights that inform the next iteration of the agent. This post describes how UAEF works, provides a playbook for choosing metrics and preparing datasets, and points to runnable notebooks for each supported framework.
UAEF: One evaluation layer for agent frameworks
UAEF is a framework-agnostic evaluation system for AI agents. It takes the agent a team already has and scores it the same way across supported frameworks and runtimes. UAEF takes two inputs: the agent under test and a dataset to run it on. The dataset provides the inputs for each test case, and it can also include ground-truth answers, the expected output for each input. Ground truth is optional, and only metrics that compare the agent’s response against a reference use it. To evaluate tool calling, the ground truth must also include the expected tool calls for each test case: which tools the agent should call, in what order, and with what arguments. Everything after that happens inside the UAEF.
Figure 1 shows the path a single evaluation takes, from the inputs to the reports and insights. First, an adapter reads the agent’s native execution, its messages, tool calls, and agent-to-agent handoffs, and normalizes it into one canonical trace, so that the steps that follow are identical no matter which framework produced the agent. Next, UAEF screens the trace for personally identifiable information (PII), such as email addresses, phone numbers, and credit card numbers, before data is stored. The evaluation engine then scores the trace on a selection from 36 built-in metrics across 7 quality dimensions. When you persist a run, UAEF records it as an experiment in Amazon DynamoDB and Amazon S3: Amazon DynamoDB holds the per-experiment metadata used for listing and comparison, and Amazon S3 holds the full results. With runs stored, a team can compare an agent version against a baseline to detect regressions and generate reports and insights that explain what changed and why. Those reports close the loop: the team evaluates the agent, learns what regressed or improved, changes the prompt, model, or tools, and evaluates again.
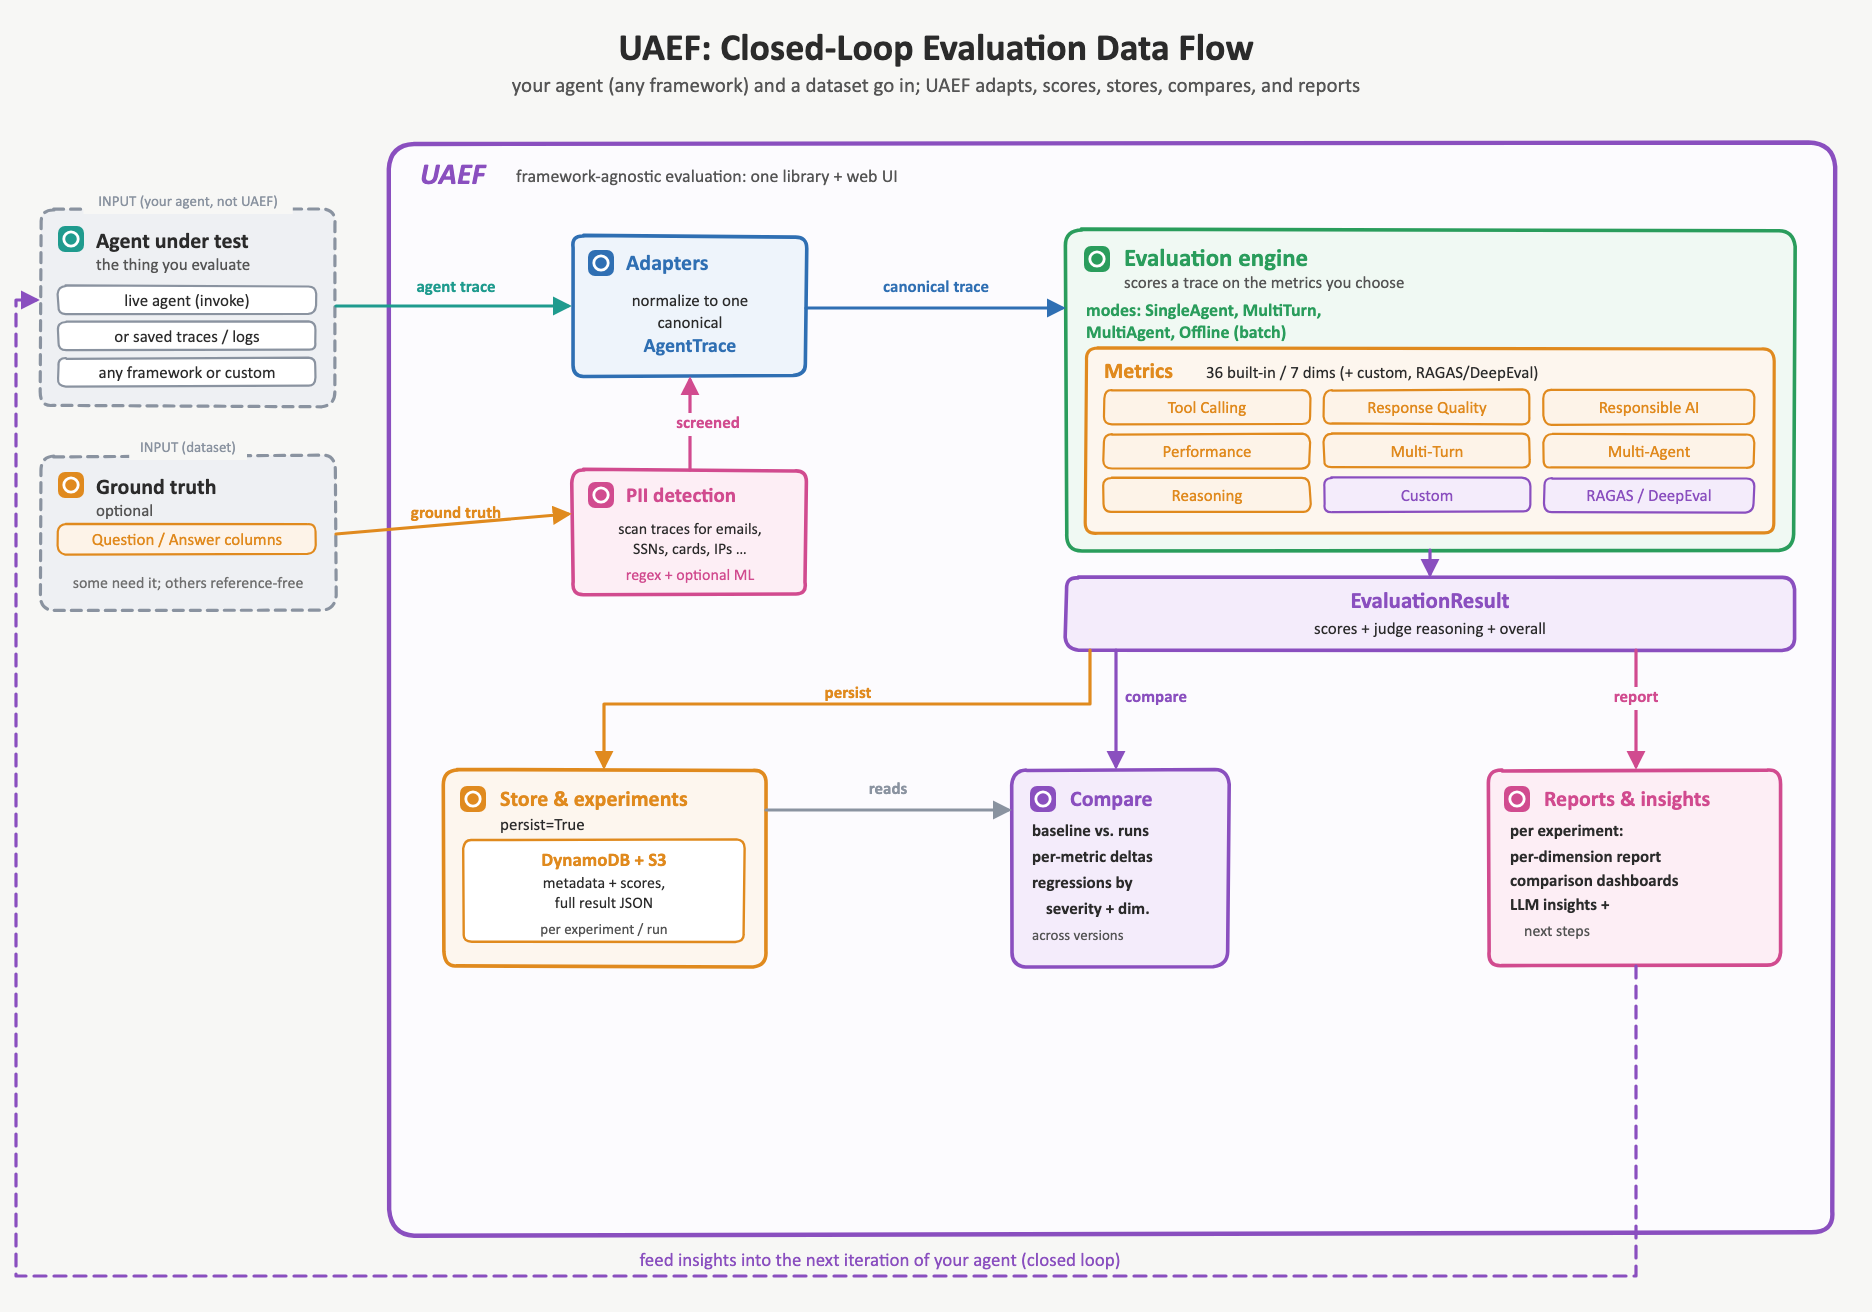
Figure 1: UAEF closed-loop evaluation data flow
The rest of this section follows that flow in order: the adapters that make UAEF framework-agnostic, the evaluation engine and its metrics, PII detection, experiment storage and comparison, and the reports that close the loop.
Canonical trace and adapters
Adapters are what make UAEF framework-agnostic. An adapter reads the record of an agent’s run, including its messages, tool calls, and agent-to-agent handoffs. It converts that record into one canonical representation called the AgentTrace, which is the only thing the rest of UAEF scores. Because of that conversion, UAEF works with the agent, whatever SDK it was built with (such as LangGraph, LangChain, or Strands Agents). It can run locally, behind an HTTP endpoint, or on a managed runtime such as Amazon Bedrock AgentCore, with traces in Langfuse or not captured at all. UAEF provides an adapter for each of these, and they produce the same AgentTrace, so metrics, scores, and comparisons stay consistent across every one of them.
A trace reaches UAEF two ways. If one already exists, from a past run, a log, or an observability store, it is handed to UAEF and the matching adapter normalizes it. If not, UAEF invokes the agent for you: given a runtime Amazon Resource Name (ARN) or an HTTP endpoint, it calls the agent on each dataset input, collects the response, and adapts it in one step. Either way, the output is the same AgentTrace.
Because every metric, mode, and report operates on the AgentTrace rather than on a framework native format, the scoring that follows is identical no matter where the trace came from. That separation, normalization first and scoring second, is what lets a team compare an agent built on one framework against an agent built on another on a single scale.
Evaluation engine
The evaluation engine scores a canonical trace across 7 quality dimensions, each capturing a distinct aspect of agent behavior that a single accuracy number would hide. Tool calling measures whether the agent selected the right tools, called them in a sensible order, and passed valid arguments. Response quality measures whether the final answer is relevant, complete, accurate, and grounded in the provided context rather than hallucinated.
Responsible AI measures safety, bias, toxicity, and resistance to prompt injection. Performance measures operational cost in latency, token use, and throughput. Multi-turn measures how well the agent sustains a conversation, including context retention, coherence, and goal completion across turns. Multi-agent measures coordination in systems of cooperating agents, such as task delegation and the division of work. Reasoning measures the internal logic of the agent’s chain of thought, including consistency and freedom from fallacies.
Each dimension is computed by one or more of 36 built-in metrics, and every metric returns a normalized score in the interval [0, 1], where 1 is best, so dimensions and the overall result share one scale. Metrics come in two families. Deterministic metrics compute a score directly from the trace and the ground truth and reproduce exactly on repeated runs. Large language model (LLM)-as-a-judge metrics score qualities that resist a closed-form definition, such as response relevance or safety, by prompting a judge model on Amazon Bedrock. You can also add your own custom metrics or draw on the RAGAS and DeepEval integrations.
Because judge metrics feed an agent’s own output back into a prompt, that content is treated as untrusted input: an agent that can influence its judge can influence its own scores. The rubric is sent separately from the content, and the content is escaped so it cannot break out of its delimiter and be read as instructions. Each judge response is parsed strictly and must cite a verbatim span of the content it scored. A score whose evidence is not found is rejected rather than recorded. Judge scores are evaluation signal, not a safety decision, and should not gate a security control. For runtime enforcement on the agent itself, apply Amazon Bedrock Guardrails in its own invocation path. The full model is in SECURITY.md.
Experiment management and comparison
UAEF records each evaluation as an experiment, so results from different agent versions can be compared later. Calling evaluate() or batch_evaluate() with persist=True creates a new experiment, identified by an optional name and objective, and writes it to two stores with complementary roles. Amazon DynamoDB holds one row per experiment with the metadata used for listing and comparison: evaluation count, the average score per metric, and an overall average. Amazon S3 holds a JSON file with the full evaluation results, including per-metric scores and the judge’s reasoning. Teams that handle sensitive data can turn on PII redaction for the stored copy.
The Python library also models a finer-grained structure. An experiment contains runs, and each run records the agent design under test: framework, model, tools, system prompt, and parameters. A run can also record a configuration snapshot and a Git commit. You can mark one run as the baseline for its experiment. This ties each score to the change that produced it, whether a new prompt, a different model, or an added tool.
Comparison works on the stored per-metric averages. For each metric that two runs have in common, the comparison engine calculates the absolute and percentage change. It then classifies the metric as a regression, an improvement, or unchanged, using a configurable threshold with a default of 5 percent. Several runs can be compared against a single baseline in one call. The regression detector also assigns a severity to each regression: minor (5–10 percent), moderate (10–20 percent), or severe (over 20 percent). It groups regressions by dimension, which shows, for example, whether a prompt change affected tool calling but not response quality.
In the web UI, the Compare tab lists stored experiments and filters them by framework or dataset. You select two or more experiments. The first is used as the baseline, and the UI shows per-metric scores with regressions and improvements highlighted. The UI calls the same library comparison engine, so results match what the Python API returns.
Report and insight generation
After an evaluation is stored, UAEF reports on it at three levels, each answering a different question. How did this run perform? Why did it score that way? How does it compare with earlier versions?
Results view. When an evaluation finishes, the web UI shows a summary of the experiment: the overall score, the number of test cases evaluated, the framework, and queries that failed to run. Per-metric averages appear with a dimension radar chart and a metric bar chart. A table lists every test case with its query, the agent’s response, the expected answer, and the score. Expanding a row shows the full response with its dimension and metric scores. For a multi-turn conversation, it shows each turn with its own scores and the tools the agent called.
Detailed report. From the results view or the experiment list, you can generate a statistical report on demand. UAEF loads the stored results from Amazon S3 and opens the report in a new browser tab. The report breaks results down by dimension and by metric. It shows confidence intervals and outliers for each metric, score distributions, correlations between metrics, a responsible AI summary, and test cases that reported failures. It closes with recommendations that point to the lowest-scoring dimensions and the metrics that vary most across test cases. The report is computed from the scores alone, without an LLM, so the same results produce the same report.
LLM-generated insights. In the Python library, you can pass a report to a model on Amazon Bedrock for analysis. For a single run, the analysis covers strengths, critical weaknesses, hypotheses about root causes, and prioritized recommendations. For a comparison of several runs, it covers the overall trend, likely causes of regressions and improvements, the risk each regression carries, and next steps. These insights suggest what to change in the prompt, model, or tools before the next evaluation.
Two ways to use it
You can run UAEF two ways over the same engine. With the Python library, you can evaluate agents in code from notebooks, scripts, and continuous integration and continuous delivery (CI/CD) pipelines. You can use the deployable AWS service to evaluate agents through a low-code web interface. You upload your dataset, select a framework and metrics, run the evaluation, and review the scores. Both paths run the identical evaluation engine and write to the same stores, so a result does not depend on which path produced it. You can start in the interface and move to code without changing how your results are scored or compared.
Evaluating agents with UAEF: A playbook
Knowing what UAEF can measure is different from knowing what you should measure. A travel-booking agent and a policy Q&A agent fail in different ways, and scoring both on every dimension wastes time and Amazon Bedrock invocations. Use this playbook to pick the metrics that match your agent, then add more as new questions come up.
Getting started
UAEF is open source under the Apache 2.0 license in the awslabs/uaef GitHub repository. It includes the Python library, framework adapters, built-in metrics, AWS Cloud Development Kit (AWS CDK) infrastructure for the deployable service, the web interface, and runnable notebooks for each supported framework. The Installation Guide covers requirements, installing from a built package, and the development setup.
The service deployment guide covers deploying UAEF as a service with the web interface, the config reference, and teardown.
See it in action
A complete evaluation in the UAEF web interface, from ground-truth upload to per-dimension scores.
Choosing the metrics
Start from your scenario, not the metric list. Find the column that matches your agent and begin with the metrics checked in it. The Needs ground truth column shows which metrics compare against a reference answer or expected tool calls.
Dimension
Metric
Needs ground truth
Scenarios
RAG / knowledge Q&A
General Q&A
Tool-using agent
Multi-turn conversation
Reasoning
Safety and compliance
Multi-agent
Production monitoring
Response Quality
answer_relevance
accuracy
completeness
hallucination_score
ragas_faithfulness
ragas_context_precision
ragas_context_recall
Tool Calling
tool_selection_accuracy
tool_sequence_correctness
parameter_quality
mcp_compliance
Multi-Turn
context_retention
coherence
conversation_completeness
user_satisfaction
turn_efficiency
Reasoning
chain_of_thought_coherence
logical_consistency
reasoning_step_correctness
fallacy_detection
Responsible AI
safety_score
toxicity_score
bias_score
prompt_injection_detection
Multi-Agent
workflow_completion
delegation_quality
agent_utilization
coordination_efficiency
Performance
latency_score
token_efficiency
cost_efficiency
throughput
The table shows recommended starting metrics for each scenario. For the complete list of supported metrics, see the metrics catalog.
Pass the metrics you picked as the metrics argument to evaluate() or batch_evaluate(). For a worked example, see the Example notebooks section that follows. Deterministic metrics, such as tool calling and performance, are computed directly from the trace, whereas others call an LLM judge. UAEF automatically skips metrics that need a reference answer when no ground truth is present, so partially labeled datasets and unlabeled production traffic are still worth evaluating.
Choosing the pipeline
Metrics decide what you measure. Six independent choices decide how the evaluation runs. Use the question in each row to settle it.
Choice
Ask yourself
Then use
In code
Passive or active
Do I already have traces, or do I need to generate them under controlled conditions?
Passive: evaluate a trace you already have. Active: call an invoke_* helper so UAEF runs the agent.
evaluate(trace=recorded,
adapter=“langgraph”)
or
raw = invoke_http_agent_for_framework(
ENDPOINT, query, “strands”)
One trace or a dataset
Am I debugging one case or measuring a release?
Use evaluate() for one trace or conversation. Use batch_evaluate() for a dataset.
evaluate(trace=trace)
or
batch_evaluate(traces=traces,
max_workers=4)
Single-turn or multi-turna
Does any test case depend on an earlier turn?
Multi-turn: add session_id and turn_id to the dataset and pass every turn to the adapter, which assembles each conversation.
sessions = adapter.transform_to_canonical(
turn_payloads)
batch_evaluate(traces=sessions)
Single-agent or multi-agent
Does more than one agent handle a single request?
Nothing to configure. The adapter returns an AgentTrace or MultiAgentTrace, and UAEF selects the matching evaluator.
adapter = get_adapter(FRAMEWORK)
trace = adapter.transform_to_canonical(raw)
Offline or online
Am I testing before release or monitoring production?
Offline: a prepared dataset in development and CI. Online: live conversations, scored turn by turn.
batch_evaluate(…)
or
OnlineEvaluator().evaluate_response(
trace=trace)
Ephemeral or persistedb
Will I compare this run with a later one?
Persisted: set persist=True with an experiment name. Otherwise, use the returned result.
batch_evaluate(traces=traces, persist=True,
experiment_name=“Support agent v2”)
a Multi-turn – For details, refer to the multi-turn evaluation workflow guide.
b Only persisted runs can be compared.
Preparing your dataset
Provide one row per test case in a CSV or XLSX file. Only Question is required.
Column
Required
Purpose
Question
Yes
Input sent to the agent
Answer
No
Expected response
context
No
Reference documents for retrieval-style evaluation
expected_tool_calls
No
Expected tool calls as a JSON array
session_id
Multi-turn only
Groups rows into one conversation
turn_id
Multi-turn only
Orders turns within a conversation, starting at 1
Question and Answer are matched case-insensitively and accept common aliases such as Query and Expected_Output, so existing test files usually work without renaming.
Multi-turn datasets. Rows that share a session_id are sent in order to a single agent session, so later turns can depend on earlier ones. Your agent endpoint must maintain its own conversation state, because UAEF sends each turn with its session ID rather than replaying history. Use lowercase session_id and turn_id. Otherwise, the file is evaluated as single-turn.
Protect sensitive data. Before sharing or persisting a dataset drawn from real traffic, use uaef.security.PIIDetector to detect and redact personally identifiable information such as email addresses, phone numbers, and credit card numbers.
Example notebooks
If you want to see more examples, check our notebooks/ folder. The notebooks cover scenarios such as batch evaluation, multi-turn conversations, multi-agent, and experiment management across frameworks including LangGraph, Strands Agents, and Amazon Bedrock AgentCore.
Notebook
What it covers
00_langgraph.ipynb
LangGraph: single, batch, multi-turn, and multi-agent evaluation
02_langchain.ipynb
LangChain agents
04_json.ipynb
Custom frameworks, through the generic JSON adapter
05_strands.ipynb
Strands Agents, including multi-agent
06_agentcore.ipynb
Amazon Bedrock AgentCore, including multi-agent
07_langfuse.ipynb
Traces already collected in Langfuse
01_langgraph_ragas_deepeval.ipynb
RAGAS and DeepEval integrations
08_experiment_management.ipynb
Experiments, baselines, and regression detection
10_reporting_pipeline.ipynb
Reports and dashboards from stored results
11_pii_detection.ipynb
PII detection and redaction in traces
Clean up
Running the library creates nothing on its own, but persisting a run writes experiment metadata to Amazon DynamoDB and full results to Amazon S3. Delete both when you no longer need the saved experiments. The default names are uaef-experiments and uaef-results, overridable through the UAEF_DYNAMODB_TABLE and UAEF_S3_BUCKET environment variables. The bucket has to be emptied before it can be deleted.
If you deployed the service, the service deployment guide has the teardown sequence for both deployment modes. Read its retained-resources note before you assume teardown is complete: the DynamoDB tables, S3 buckets, and Amazon Cognito user pool are created with a retain policy, so deleting the stack leaves them, and their contents, in place. That is deliberate, so a teardown does not destroy saved experiments, but it means the storage keeps costing you until you remove it yourself.
Conclusion
UAEF separates agent evaluation from the framework that produced the agent. Adapters convert traces from LangGraph, LangChain, Strands Agents, Amazon Bedrock AgentCore, and Langfuse into a common format, and a generic JSON adapter handles other frameworks. The same 36 built-in metrics across 7 dimensions then apply regardless of how a team built the agent. UAEF evaluates individual traces or runs batch evaluations over historical traces, then stores results per experiment in Amazon DynamoDB and Amazon S3. Teams can then compare runs across agent versions, detect regressions, and use the generated reports and insights to decide what to change in the next iteration. The web UI and the Python library share the same evaluation engine, so teams can start low-code and move to code without changing how scoring or storage works.
To get started, see the open source repository.
About the authors

 Studio