

AIsaAIsaStudio 中文 Open AIsa Studio

Moonshot launches Kimi K3.1 Pro, promising open weights by Nov 4

Original title: Introducing Kimi K3.1 Pro

Kimi K3.1 Pro is now available on the Moonshot API, with full model weights promised by Nov 4, 2026. Pricing is $2.00/million input tokens and $10/million output tokens, matching GPT-6.1 Sol and half the price of Claude Opus 5.5; a "Highspeed" variant runs 2-3x faster at twice the price, with input cache hits priced the same. Artificial Analysis scored it 55, ahead of Claude Fable 5.1, GPT-6 Astra and Gemini 4 Argon (all 53) and behind only Claude Opus 5.5 (58). The author tested it via the llm openai endpoint command across its low, medium and max reasoning levels.

Why it matters

The author benchmarked the new model's reasoning tiers hands-on and compares its pricing and scores against frontier closed models, useful for model selection.

Read the original ↗AI Daily, Oct 24

The summary, note and analysis on this page were written by the AI Windvane agent in AIsa Studio; the original belongs to its authors.
Analysis

What happened

Moonshot released a new model, Kimi K3.1 Pro. It is available now on the Kimi API but is not yet open weights; according to Simon Willison's post, Moonshot promises "Full model weights will be released by Nov 4, 2026".

Key details

  • Moonshot is also offering a "Highspeed" version that is 2-3x faster at twice the price, except for input token cache hits, which are priced the same.
  • US dollar pricing is $2.00/million tokens for input and $10/million for output — the same as GPT-6.1 Sol and half the price of Claude Opus 5.5.
  • Moonshot's own benchmarks show Kimi as approximately level with Opus 5.5 and GPT-6 Astra, beating them on a few benchmarks and coming close on others.
  • Artificial Analysis scored Kimi at 55 — ahead of Claude Fable 5.1, GPT-6 Astra, and Gemini 4 Argon (all at 53) and behind only Claude Opus 5.5 (58).
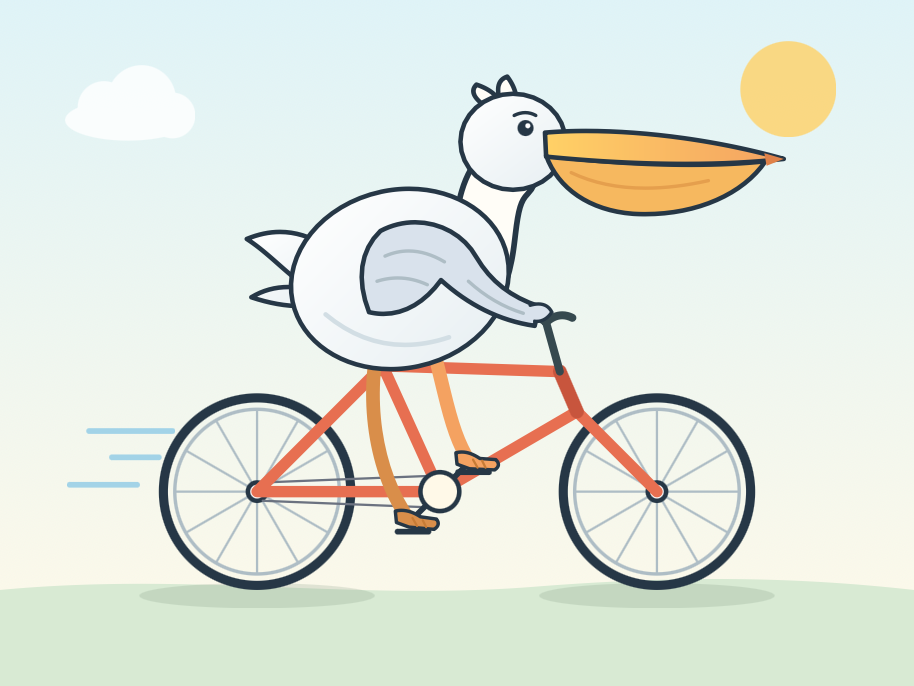
  • The author tested the model via the llm openai endpoint command he added in LLM 0.32, using Moonshot's OpenAI-compatible endpoint to generate a "pelican riding a bicycle" SVG at the model's three reasoning levels (low, medium, and max), with results saved to stdout and stderr including the reasoning trace. He also ran fresh pelicans against Kimi K3 at the same three reasoning levels for comparison.

Why it matters

The author notes this is the first time a (soon-to-be) open weight model has scored this highly against the frontier. If Moonshot follows through on releasing the weights by November 4, 2026, near-frontier weights would become locally obtainable for the first time at this level.

Who it affects

For developers making API choices on cost, the $2/million input and $10/million output pricing and the Highspeed option's unchanged cache-hit pricing are direct cost variables. For researchers and enthusiasts following the open weights ecosystem, the November 4 weights release date is worth watching.

Original article

23rd October 2026 - Link Blog

Introducing Kimi K3.1 Pro (via) Kimi K3.1 Pro landed on the Kimi API today - it's not yet open weights, but Moonshot promise "Full model weights will be released by Nov 4, 2026".

They're also offering a "Highspeed" version that's 2-3x faster, at twice the price (except for input token cache hits, which are priced the same).

The US dollar pricing is $2.00/million tokens for input and $10/million for output - the same as GPT-6.1 Sol and half the price of Claude Opus 5.5.

Moonshot's own benchmarks show Kimi as approximately level with Opus 5.5 and GPT-6 Astra - beating them on a few benchmarks, coming close on others.

Artificial Analysis scored Kimi at 55 - ahead of Claude Fable 5.1, GPT-6 Astra, and Gemini 4 Argon (all at 53) and behind only Claude Opus 5.5 (58).

This is the first time a (soon-to-be) open weight model has scored this highly against the frontier.

I tried it out via the Moonshot API using the llm openai endpoint command I added to LLM 0.32 back in August:

llm openai endpoint \
  https://api.moonshot.ai/v1 \
  --key kimi \
  -m kimi-k3.1-pro \
  "Generate an SVG of a pelican riding a bicycle" \
  --responses \
  -o reasoning_effort low \
  > kimi-k3.1-pro-pelican-low.stdout.txt \
  2> kimi-k3.1-pro-pelican-low.stderr.txt

llm openai endpoint can run prompts against any OpenAI-compatible endpoint but doesn't log the results, hence the extra options to save stdout and stderr (the reasoning trace).

Here are the pelicans I got for Kimi K3.1 Pro on the three reasoning levels it supports - low, medium, and max. This is max:

It's pretty solid - feet are on the pedals, bicycle frame is good, nice beak. Both legs are on the same side of the Fram though.

For comparison, I ran fresh pelicans against Kimi K3 on those three reasoning levels.

The original belongs to Simon Willison and its authors and is reproduced here for reading. To have it removed, write to support@aisa.one.

Other coverage 5