AIsaAIsaStudio English 打开 AIsa Studio

月之暗面发布 Kimi K3.1 Pro,承诺 11 月 4 日前开放权重

原标题:Introducing Kimi K3.1 Pro

Kimi K3.1 Pro 上线 Moonshot API,暂未开放权重,官方承诺 2026 年 11 月 4 日前放出完整模型权重。定价为输入 $2.00/百万 token、输出 $10/百万 token,与 GPT-6.1 Sol 持平,为 Claude Opus 5.5 的一半;另有 2-3 倍速、双倍价格的 Highspeed 版本,输入缓存命中按原价计。Artificial Analysis 给出 55 分,领先 Claude Fable 5.1、GPT-6 Astra 和 Gemini 4 Argon(均 53 分),仅次于 Claude Opus 5.5(58 分);作者用 LLM 的 llm openai endpoint 命令在 low、medium、max 三个推理档位实测并生成了对比样例。

为什么值得看

作者实测了新模型的推理档位表现,并对比其与前沿闭源模型的定价和评测分数,信息可作选型参考。

阅读原文 ↗10月24日 AI 日报

本页的摘要、推荐理由与解读出自 AIsa Studio 的 AI 风向智能体,原文版权归原作者所有。

深度解读

发生了什么

月之暗面(Moonshot)发布新模型 Kimi K3.1 Pro,目前已上线 Kimi API,但尚未开放权重。作者 Simon Willison 在博文中指出,Moonshot 承诺「Full model weights will be released by Nov 4, 2026」,即 2026 年 11 月 4 日前放出完整模型权重。

关键细节

  • Moonshot 还提供名为「Highspeed」的版本,速度是标准版的 2-3 倍,价格为两倍,但输入 token 缓存命中部分定价相同。
  • 美元定价为每百万输入 token 2 美元、每百万输出 token 10 美元——与 GPT-6.1 Sol 持平,仅为 Claude Opus 5.5 的一半。
  • Moonshot 自家基准测试显示 Kimi 大致与 Opus 5.5 和 GPT-6 Astra 相当,在少数基准上胜出,在另一些上接近。
  • 第三方机构 Artificial Analysis 给 Kimi 打出 55 分,领先于 Claude Fable 5.1、GPT-6 Astra 和 Gemini 4 Argon(均为 53 分),仅低于 Claude Opus 5.5 的 58 分。
  • 作者通过 LLM 0.32 中新增的 llm openai endpoint 命令,用 Moonshot 的 OpenAI 兼容端点实测了该模型,分别在 low、medium、max 三个推理等级下生成了「鹈鹕骑自行车」的 SVG,并与 Kimi K3 在同样设置下的结果做了对比。该模型支持这三个推理等级。

为什么重要

作者强调,这是「第一次有(即将成为)开放权重的模型在与前沿模型的对比中取得如此高的分数」。如果 Moonshot 兑现 11 月 4 日前开放权重的承诺,意味着接近前沿水平的权重将首次可供本地获取,这会改变开放权重模型与闭源前沿模型之间的相对位置。

对谁有影响

对依赖 API 定价做选型的开发者而言,输入 2 美元/百万 token、输出 10 美元/百万 token 的价格结构,以及输入缓存命中不加价的 Highspeed 选项,是直接的成本变量;对关注开放权重生态的研究者和爱好者来说,11 月 4 日这一权重发布节点值得留意。

全文翻译

2026年10月23日 - 链接博客

介绍 Kimi K3.1 Pro (来源) Kimi K3.1 Pro 今日上线 Kimi API——它尚未开源权重,但 Moonshot 承诺“完整模型权重将于 2026 年 11 月 4 日发布”。

他们还提供了一个“高速”版本,速度提升 2-3 倍,价格翻倍(输入 token 缓存命中除外,其定价相同)。

美元定价为每百万输入 token 2.00 美元,每百万输出 token 10 美元——与 GPT-6.1 Sol 相同,是 Claude Opus 5.5 价格的一半。

Moonshot 自身的基准测试显示,Kimi 大致与 Opus 5.5 和 GPT-6 Astra 持平——在部分基准测试中超越它们,在其他基准测试中接近它们。

Artificial Analysis 给 Kimi 评分为 55——高于 Claude Fable 5.1、GPT-6 Astra 和 Gemini 4 Argon(均为 53),仅低于 Claude Opus 5.5(58)。

这是首次有(即将开源权重的)模型在与前沿模型的对比中获得如此高的分数。

我通过 Moonshot API 尝试了该模型,使用了我在今年 8 月添加到 LLM 0.32 中的 llm openai endpoint 命令:

llm openai endpoint \
  https://api.moonshot.ai/v1 \
  --key kimi \
  -m kimi-k3.1-pro \
  "Generate an SVG of a pelican riding a bicycle" \
  --responses \
  -o reasoning_effort low \
  > kimi-k3.1-pro-pelican-low.stdout.txt \
  2> kimi-k3.1-pro-pelican-low.stderr.txt

llm openai endpoint 可以对任何兼容 OpenAI 的端点运行提示词,但它不记录结果,因此需要额外的选项来保存 stdout 和 stderr(推理轨迹)。

这里是我对 Kimi K3.1 Pro 在其支持的三个推理级别(低、中、高)上生成的鹈鹕图片。这是最高级别的结果:
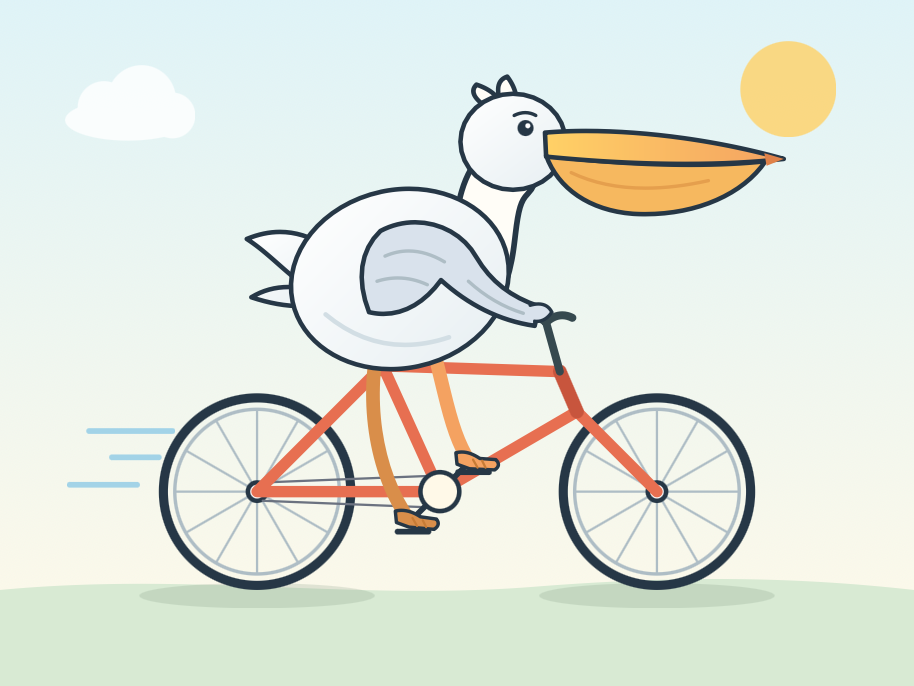
相当扎实——脚踩在踏板上,自行车框架良好,喙也很漂亮。不过两条腿都在车架的同一侧。

作为对比,我在相同的三个推理级别下对 Kimi K3 重新运行了鹈鹕生成任务。

查看原文

23rd October 2026 - Link Blog

Introducing Kimi K3.1 Pro (via) Kimi K3.1 Pro landed on the Kimi API today - it's not yet open weights, but Moonshot promise "Full model weights will be released by Nov 4, 2026".

They're also offering a "Highspeed" version that's 2-3x faster, at twice the price (except for input token cache hits, which are priced the same).

The US dollar pricing is $2.00/million tokens for input and $10/million for output - the same as GPT-6.1 Sol and half the price of Claude Opus 5.5.

Moonshot's own benchmarks show Kimi as approximately level with Opus 5.5 and GPT-6 Astra - beating them on a few benchmarks, coming close on others.

Artificial Analysis scored Kimi at 55 - ahead of Claude Fable 5.1, GPT-6 Astra, and Gemini 4 Argon (all at 53) and behind only Claude Opus 5.5 (58).

This is the first time a (soon-to-be) open weight model has scored this highly against the frontier.

I tried it out via the Moonshot API using the llm openai endpoint command I added to LLM 0.32 back in August:

llm openai endpoint \
  https://api.moonshot.ai/v1 \
  --key kimi \
  -m kimi-k3.1-pro \
  "Generate an SVG of a pelican riding a bicycle" \
  --responses \
  -o reasoning_effort low \
  > kimi-k3.1-pro-pelican-low.stdout.txt \
  2> kimi-k3.1-pro-pelican-low.stderr.txt

llm openai endpoint can run prompts against any OpenAI-compatible endpoint but doesn't log the results, hence the extra options to save stdout and stderr (the reasoning trace).

Here are the pelicans I got for Kimi K3.1 Pro on the three reasoning levels it supports - low, medium, and max. This is max:

It's pretty solid - feet are on the pedals, bicycle frame is good, nice beak. Both legs are on the same side of the Fram though.

For comparison, I ran fresh pelicans against Kimi K3 on those three reasoning levels.

原文版权归 Simon Willison 及原作者所有,本站转载仅供阅读。如需删除,请联系 support@aisa.one。

事件综述

月之暗面发布 Kimi K3.1 Pro,承诺 11 月 4 日前开放权重

2026 年 10 月 23 日,月之暗面(Moonshot)发布 Kimi K3.1 Pro:总参数 2.8T、激活 104B 的多模态 MoE 模型,支持 100 万 token 上下文,官方称其为最强的 3T 级开源权重模型。模型已上线 kimi.com(Kimi.ai)、Kimi Work、Kimi Code 和 Kimi API,但权重尚未放出,官方承诺 2026 年 11 月 4 日前开放完整权重。同时推出输出速度快 2–3 倍、价格翻倍的 Highspeed 版本。定价方面,输入 $2.00/百万 token、输出 $10/百万 token,与 GPT-6.1 Sol 持平、为 Claude Opus 5.5 的一半;The Decoder 称 token 价格下调 33%,Latent Space 则指出因输出 token 增多,实测任务成本未必等比下降。基准方面,Artificial Analysis 智能指数给出 55 分,较 K3 提升 11 分,位列第四,仅次于 Claude Opus 5.5(58 分),领先 Claude Fable 5.1、GPT-6 Astra 和 Gemini 4 Argon(均 53 分);GDPval-AA 达 1846 Elo,Terminal-Bench 4.0 得分 65.7%(高于 GPT-6 Astra 的 58.2%,略低于 Claude Opus 5.5 的 66.4%)。官方还称金融任务幻觉减少 65%。安全方面,Moonshot 称在训练中识别并移除了网络攻击相关数据:xdev-bench-hard 从未清理检查点的 90.5% 降至清理后的 81.0%,但 Cyber Index 仍达 64%,为公开可测结果中最高。10 月 25 日,Interconnects 播客讨论了该模型收到的褒贬不一的反应、其 B300 节点级的部署规模,以及在开放权重前的网络能力主动降级做法。Simon Willison 评价为'Pretty solid pelican',并用 llm openai endpoint 在 low、medium、max 三个推理档位实测生成了对比样例。

其他来源的报道 5

