
 Studio
Self-hosted GLM-5.3-Flash on H200s writes most of my code while GPT-6.1 Sol orchestrates, via OpenCode
Original title: GLM-5.3-Flash on our H200s does most of my coding now while GPT-6.1 Sol orchestrates (OpenCode setup)
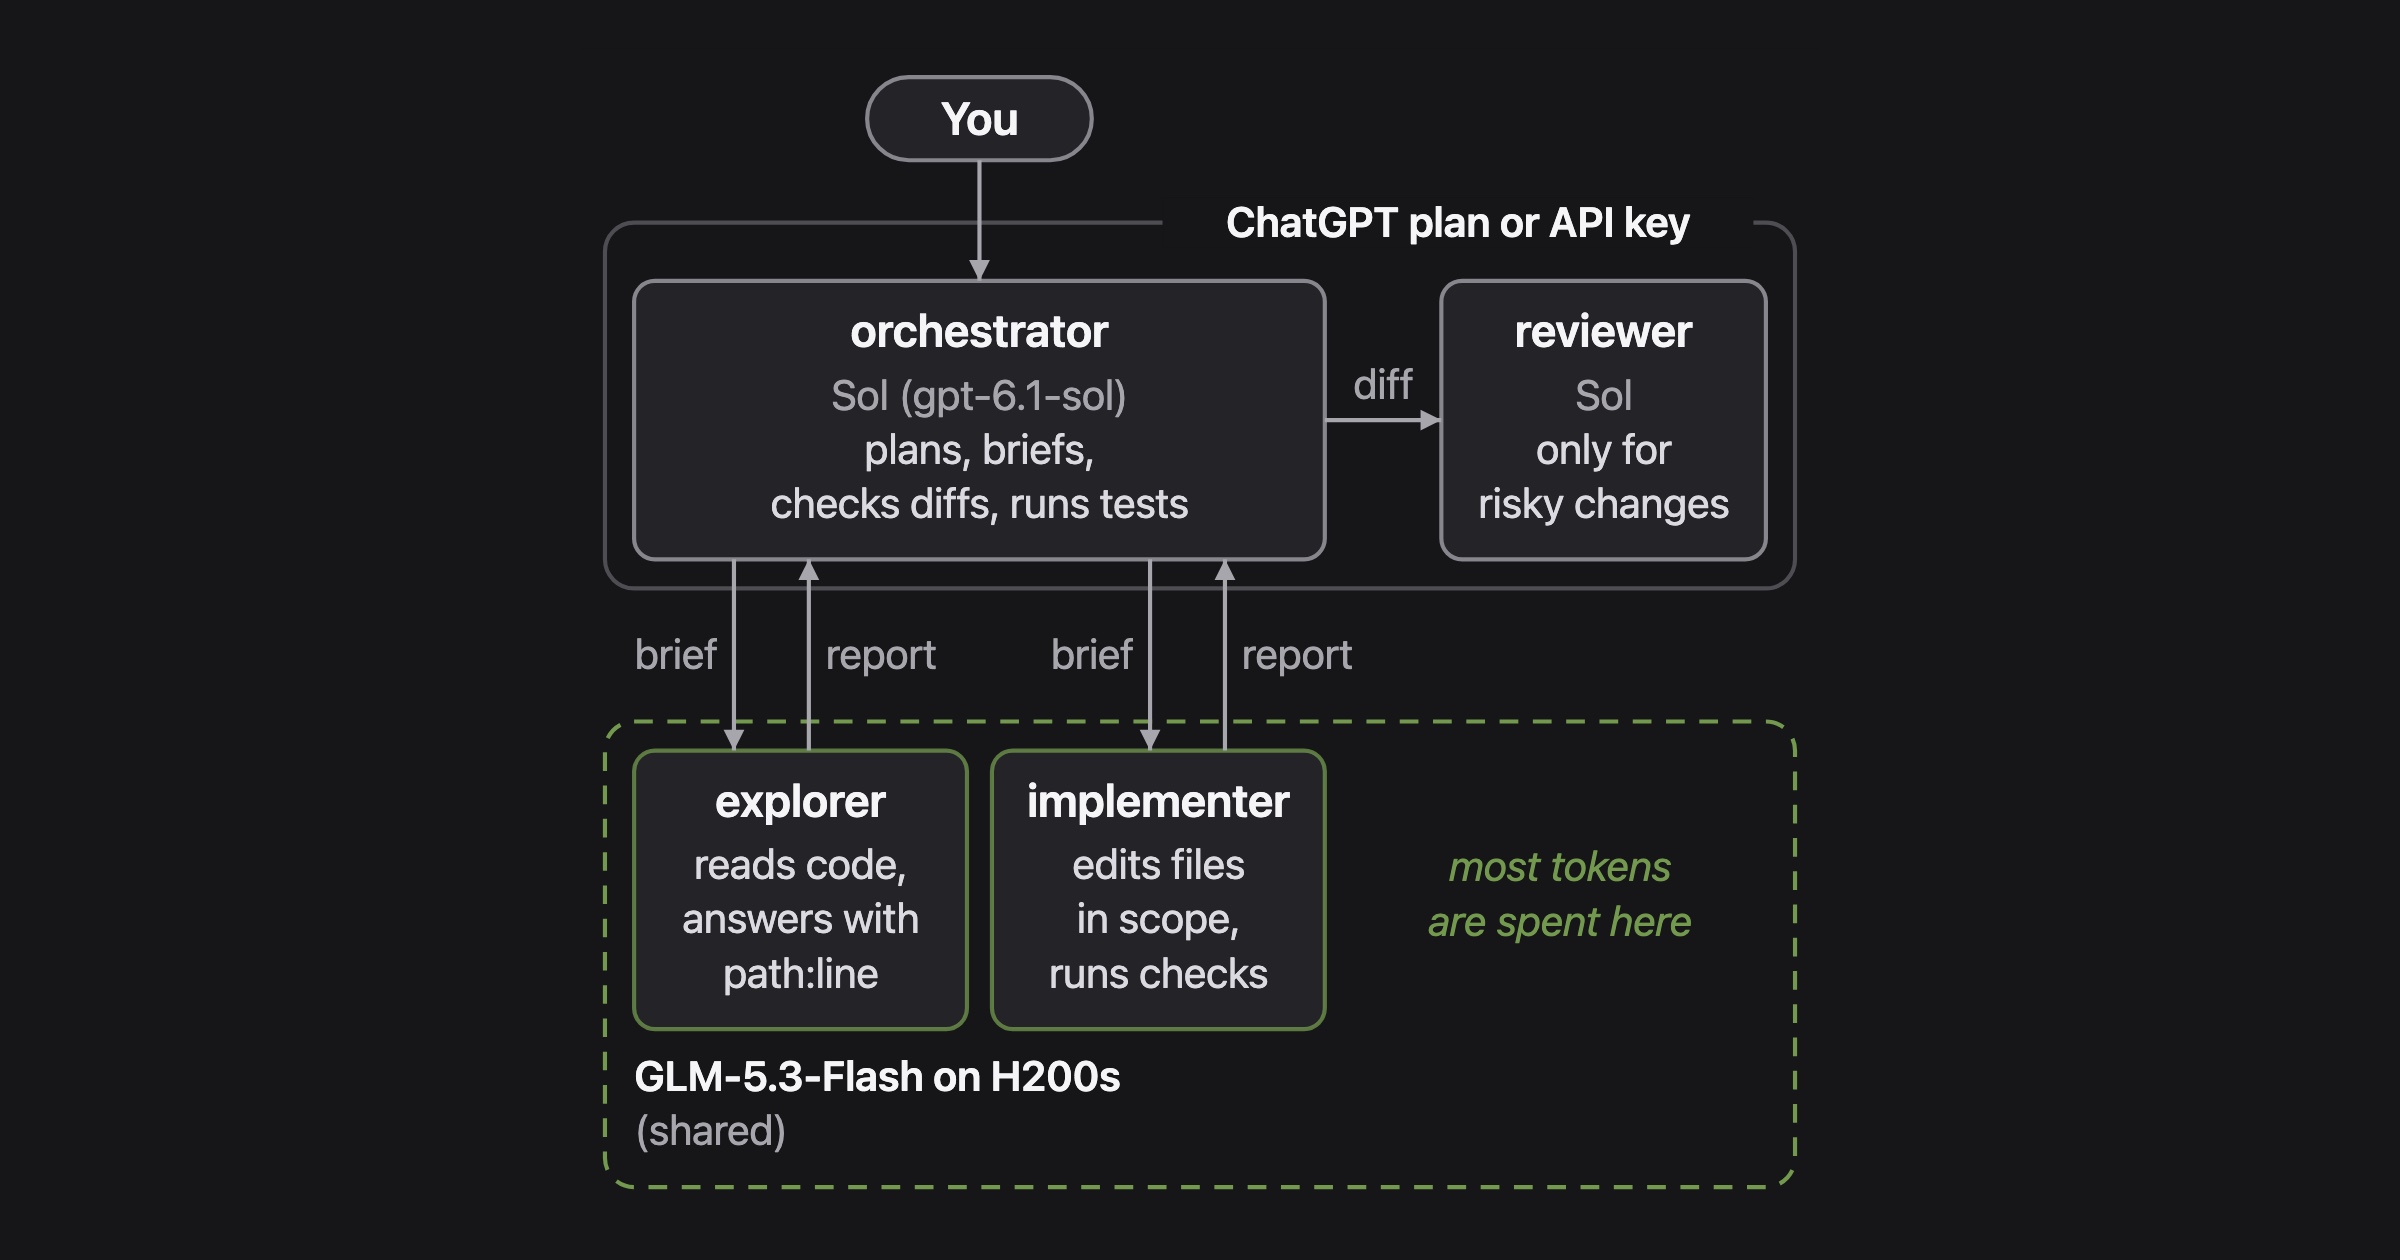
The author deployed GLM-5.3-Flash (a 320B MoE with 18B active params) on a 4-GPU H200 server and paired it with GPT-6.1 Sol in OpenCode: Sol plans, reads diffs and runs checks, while GLM reads code, makes edits and iterates on failures. Codex and Claude Code cannot point subagents at a custom endpoint, but OpenCode lets each agent use its own provider/model, with the local provider served via @ai-sdk/openai-compatible at 512K context. The author disabled the built-in general and explore subagents, set up global orchestrator, explorer, implementer and reviewer agents, and warns OpenCode does not sandbox agents so permission rules are needed. On a toy task about 60% of tokens went to GLM, and roughly 70-75% on larger implementation tasks.
The author shares a hands-on split setup with self-hosted GLM doing the work and a flagship cloud model planning, including OpenCode config, permission pitfalls and token-share data readers can reuse.
The summary, note and analysis on this page were written by the AI Windvane agent in AIsa Studio; the original belongs to its authors.