
 Studio
Mistral Large 4 technical report: aggressive KV-cache compression hurts agentic capabilities
Original title: "Mistral Large 4"
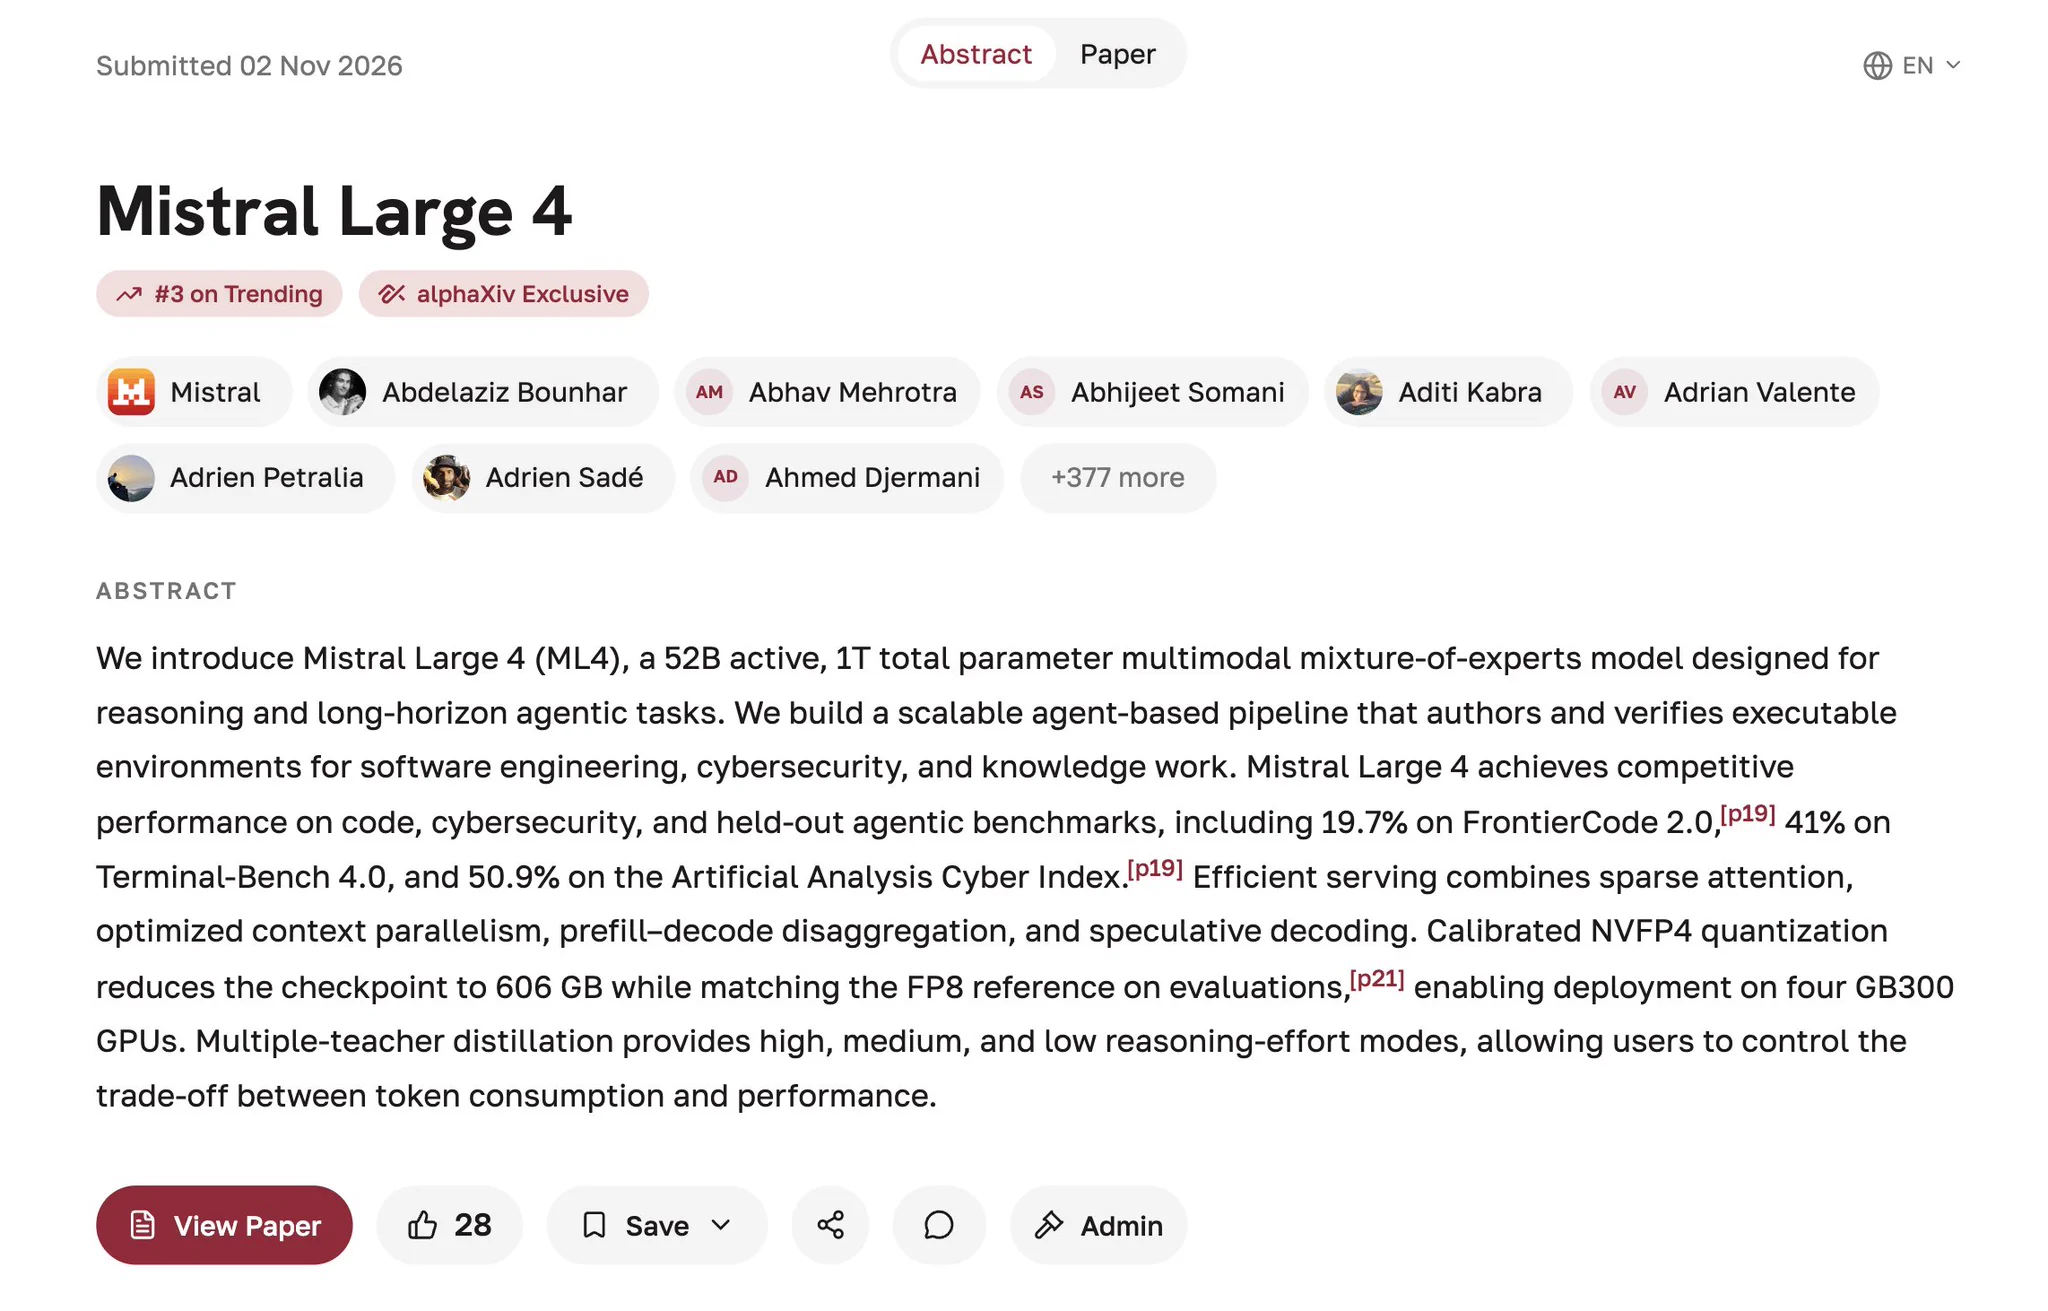
Mistral published the Mistral Large 4 technical report exclusively on alphaXiv, finding that aggressively reducing KV-cache memory can hurt long-context agentic tasks even when language modeling performance looks unchanged. After an initial 16x KV-cache reduction caused the issue, they restored full-context attention to more layers and adopted DeepSeek Sparse Attention to select the 2,048 most relevant tokens. The resulting 1T-parameter MoE model (52B active) scores 41% on Terminal-Bench 4.0 and 19.7% on FrontierCode 2.0, with its NVFP4-quantized checkpoint fitting on four GB300 GPUs.
The report shares a concrete finding that KV-cache compression degrades agentic capabilities, plus the specific fix, useful for weighing memory versus long-context trade-offs.
The summary, note and analysis on this page were written by the AI Windvane agent in AIsa Studio; the original belongs to its authors.