
 Studio
IBM releases two small open Granite 4.1 LLMON preview models trained to resist indirect prompt injection
Original title: IBM trains two small open models to ignore orders hidden in documents
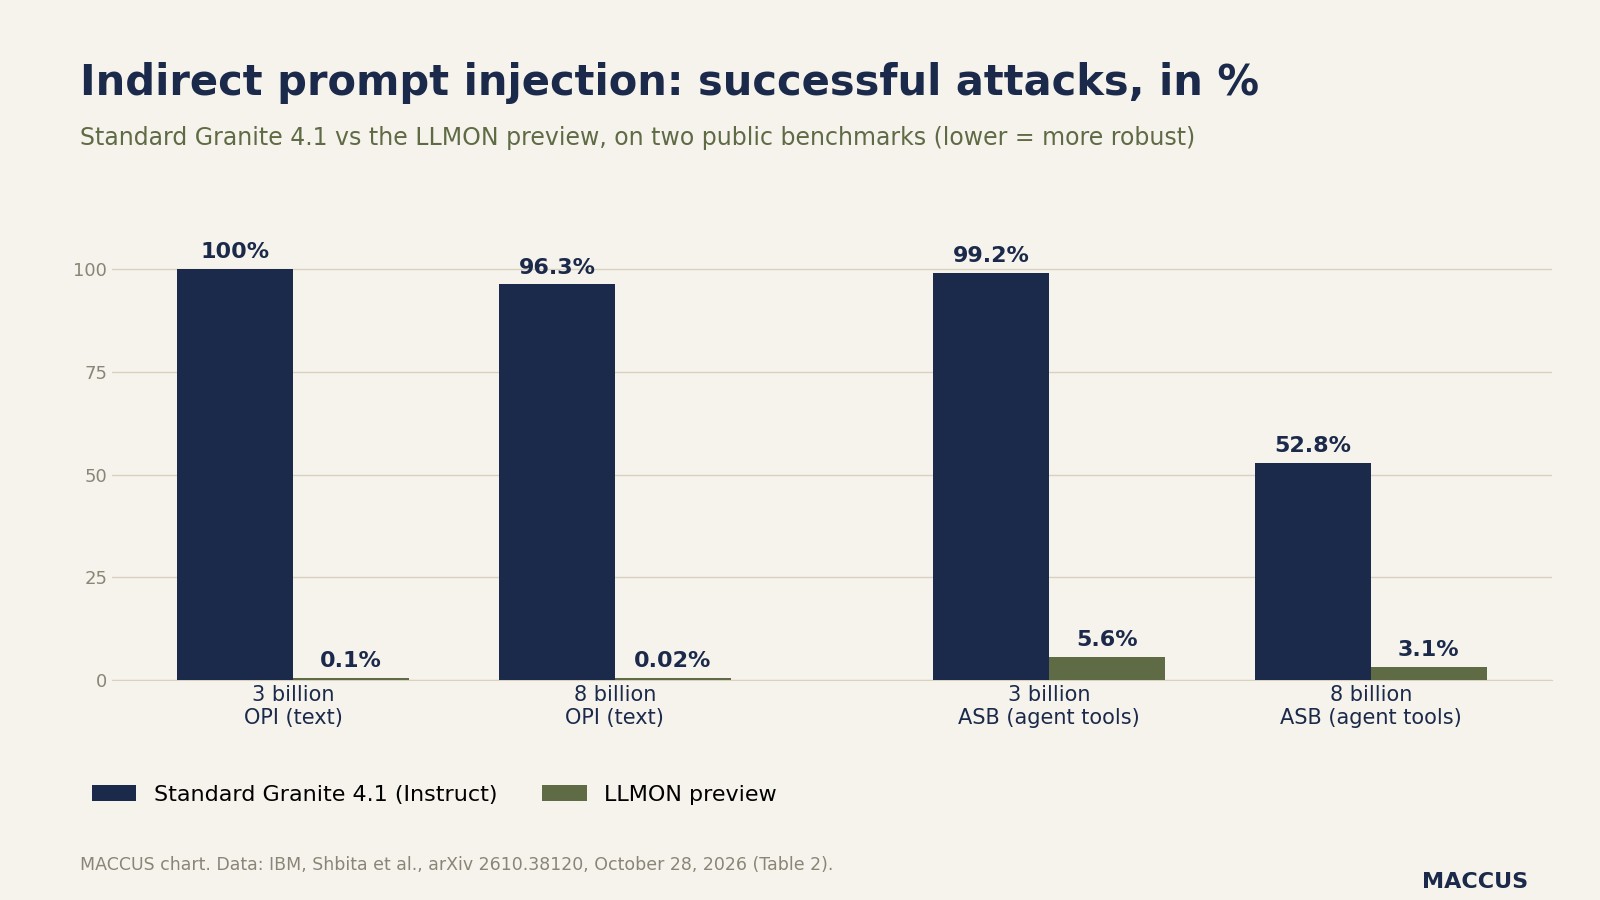
On November 12, 2026, IBM's Granite team released two open preview models, granite-4.1-3b-llmon-preview and granite-4.1-8b-llmon-preview, trained to ignore indirect prompt injections using the LLMON labeling system that separates instructions from read content. Both are Apache 2.0 licensed and downloadable from Hugging Face; on the OPI benchmark, attack success rates drop from 100% to 0.1% for the 3B model and from 96.3% to 0.02% for the 8B. IBM still limits the previews to exploration and evaluation, noting direct and multi-turn attacks remain far harder to block, and general capabilities barely changed (3B kept 66.7, 8B dropped from 74.2 to 72.8).
Drawing on IBM's model cards and papers, the article explains how the LLMON tagging scheme works, its benchmark results, and the limits IBM itself acknowledges, helping readers judge where it applies.
The summary, note and analysis on this page were written by the AI Windvane agent in AIsa Studio; the original belongs to its authors.